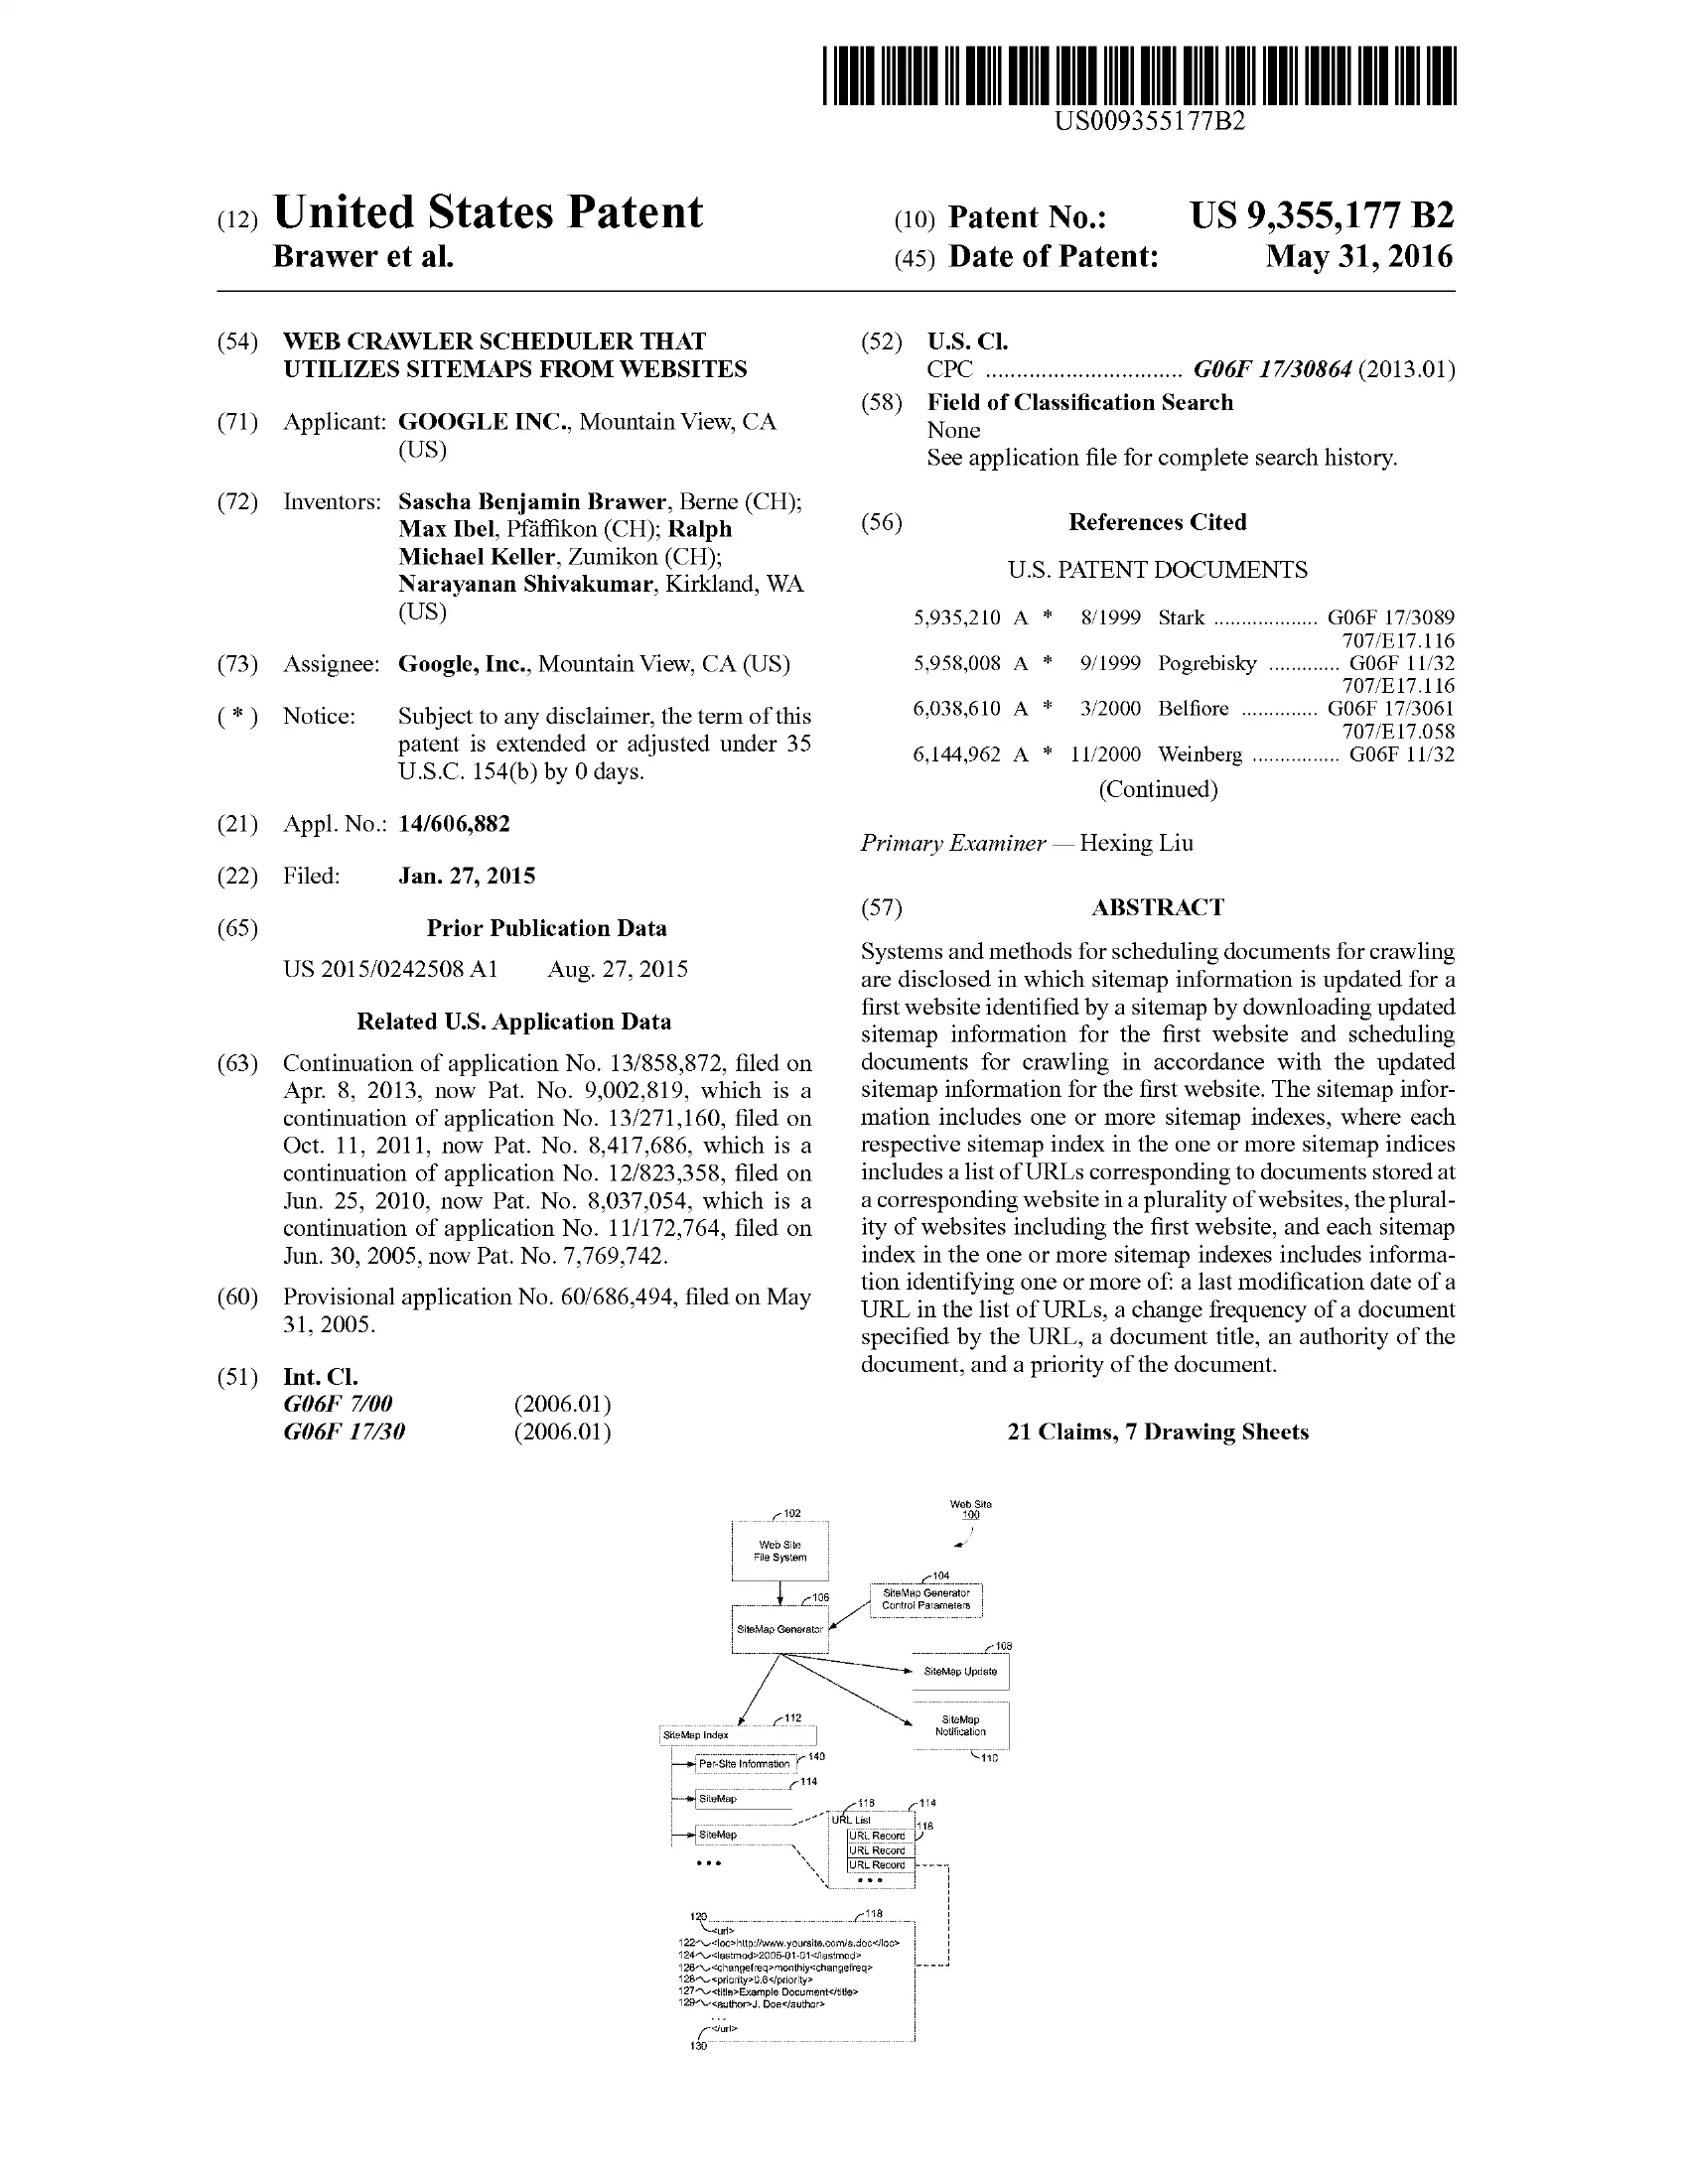
Sitemaps for Web Crawling
Free for public use since 2025.
Assigned to: Google LLC
- US 7,769,742 B1 United States lapsed 2019
- US 7,801,881 B1 United States lapsed 2019
- US 8,037,055 B2 United States expired 2025
- US 9,355,177 B2 United States lapsed 2025
Two sides of the Sitemaps mechanism for search-engine crawling. A website generates an XML file listing its URLs together with metadata — last-modified time, change frequency, relative priority — and notifies search engines that the file exists. A crawler then reads these files to discover pages it would otherwise miss, skip pages that have not changed, and stay within a site’s load limits, instead of relying on link-following alone.
The patents behind the Sitemaps protocol, co-developed at Google in 2005 and published openly as an industry standard — two US continuation threads, one for the website side and one for the crawler side.